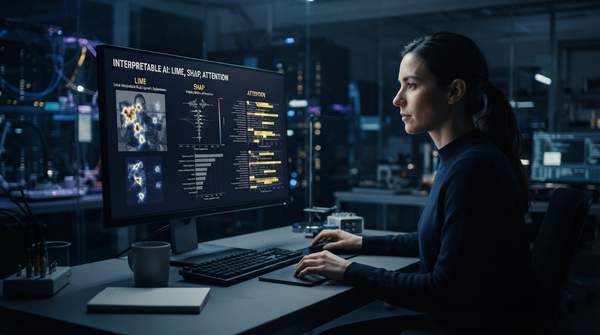
AI alignment is not one problem with one solution. Researchers pursuing it rely on a set of distinct technical strategies—robustness, interpretability, controllability, and ethicality—that attack different facets of the same question: how do we ensure an AI system does what its operators and society actually intend? IBM's technical explainer on the subject groups these four under the shorthand RICE, and each addresses a failure mode the others cannot. A robust model can still be opaque; an interpretable model can still resist correction. Understanding what each approach targets, and where each falls short, is the foundation for evaluating any AI safety proposal.
Introduction to AI Alignment: The Core Challenge
At its core, AI alignment asks how to make artificial intelligence systems act in accordance with human intentions and values. That framing sounds simple, but the field itself disagrees about what "aligned" should even mean. A 2026 position paper posted to arXiv argues that the term "AI alignment" encompasses competing rather than merely different technical ideals—ideals that, in some cases, cannot be jointly pursued. In other words, the goals bundled under alignment may pull against one another, so choosing a technical strategy is also choosing which kind of safety one prioritizes.
This is why a comparative view matters. Each technical approach answers a different question. Robustness asks whether the system behaves reliably when conditions turn hostile. Interpretability asks whether humans can see why the system decided what it did. Controllability asks whether humans can intervene, correct, or shut the system down. Ethicality asks whether the system's objectives reflect what people actually value. No single technique covers all four, which is why practical alignment work tends to layer them rather than pick a winner.
One further complication shapes everything that follows: alignment is partly a property of deployment, not just of the model. A system tuned to the norms of one cultural context can fail or cause harm when applied elsewhere, as interpretability researchers have documented. That means alignment cannot be fully "solved" at the point of model development and then forgotten—it has to be checked against the specific use, users, and context in which the system operates.